/v1/extractionsData extraction API
Pull the details you need from a post. Use a custom prompt to say what to look for and a schema to define what comes back.
Extraction docs
An API for apps and agents. Send a social post link and get the data you need in the format you choose.
 YouTube
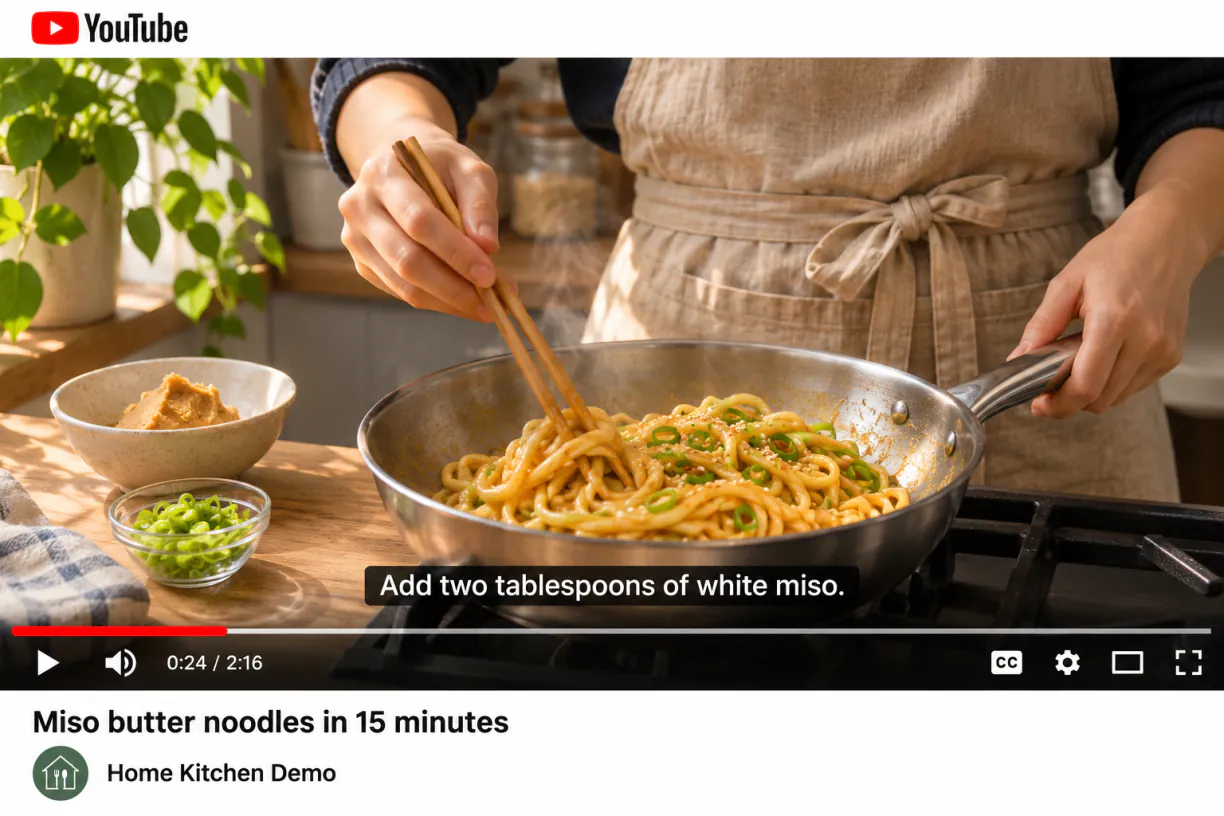
Miso butter noodles in 15 minutes
YouTube Instagram
 TikTok
 LinkedIn
 Reddit
 X
 Threads
 Facebook
 Pinterest
/v1/extractionsPull the details you need from a post. Use a custom prompt to say what to look for and a schema to define what comes back.
Extraction docs/v1/transcriptionsRetrieve existing captions or generate a transcript from the video’s audio. Choose plain text, sentence timestamps, or word timestamps.
Transcription docsWe’re building nData so apps and agents can get the data they need from different sources in a form they can use.
Launch targets are individual public posts on YouTube, Instagram, TikTok, LinkedIn, Reddit, X, Threads, Facebook, and Pinterest. Profiles, feeds, search results, and private sources are outside the current scope. Source availability depends on deployment settings, and a post may not have captions.
Configurable defaults allow videos up to 3 hours, up to 500 MB of aggregate selected media per post, and batches of up to 1,000 URLs. Credits, daily processing allowances, and other quotas still apply. These limits do not promise throughput, availability, or completion times.
New eligible personal workspaces receive 1,000 credits once, after email verification. That covers 200 extractions or 500 transcriptions at current beta rates. Daily limits apply. See beta credits and limits.
No. It uses static browser fixtures and never creates a job. Signed-in API and console submissions are separate and use the configured private processor. Read the API docs or request access if signup requires approval.
Paste a link from a supported platform to extract details or get a transcript.